제품
값싼 필터가 먼저, 비싼 검증은 그다음.
Boxdawn은 트레이스를 그래프로 읽어 2단 캐스케이드로 실행합니다. 구조 패스는 마이크로초 단위로 후보를 걸러내고, 의미 패스는 살아남은 것만 봅니다. 전체를 훑지 않습니다.
같은 에이전트가 같은 입력으로 다시 실행됩니다. 그 사이에 새로 유입된 정보는 없습니다. JSON 리포트의 비용 breakdown 에서는 provable_duplicate 로 키잉되고, 대시보드가 그 이름으로 조회하는 이유가 그것입니다. 그 옆의 waste-rate 블록은 repeat 을 씁니다.
매 API 호출마다 대화 전체가 다시 전송됩니다. 긴 에이전트 세션에서는 input 토큰의 약 97%가 재전송 컨텍스트(byte-exact 청크 매칭)로 누적됩니다.
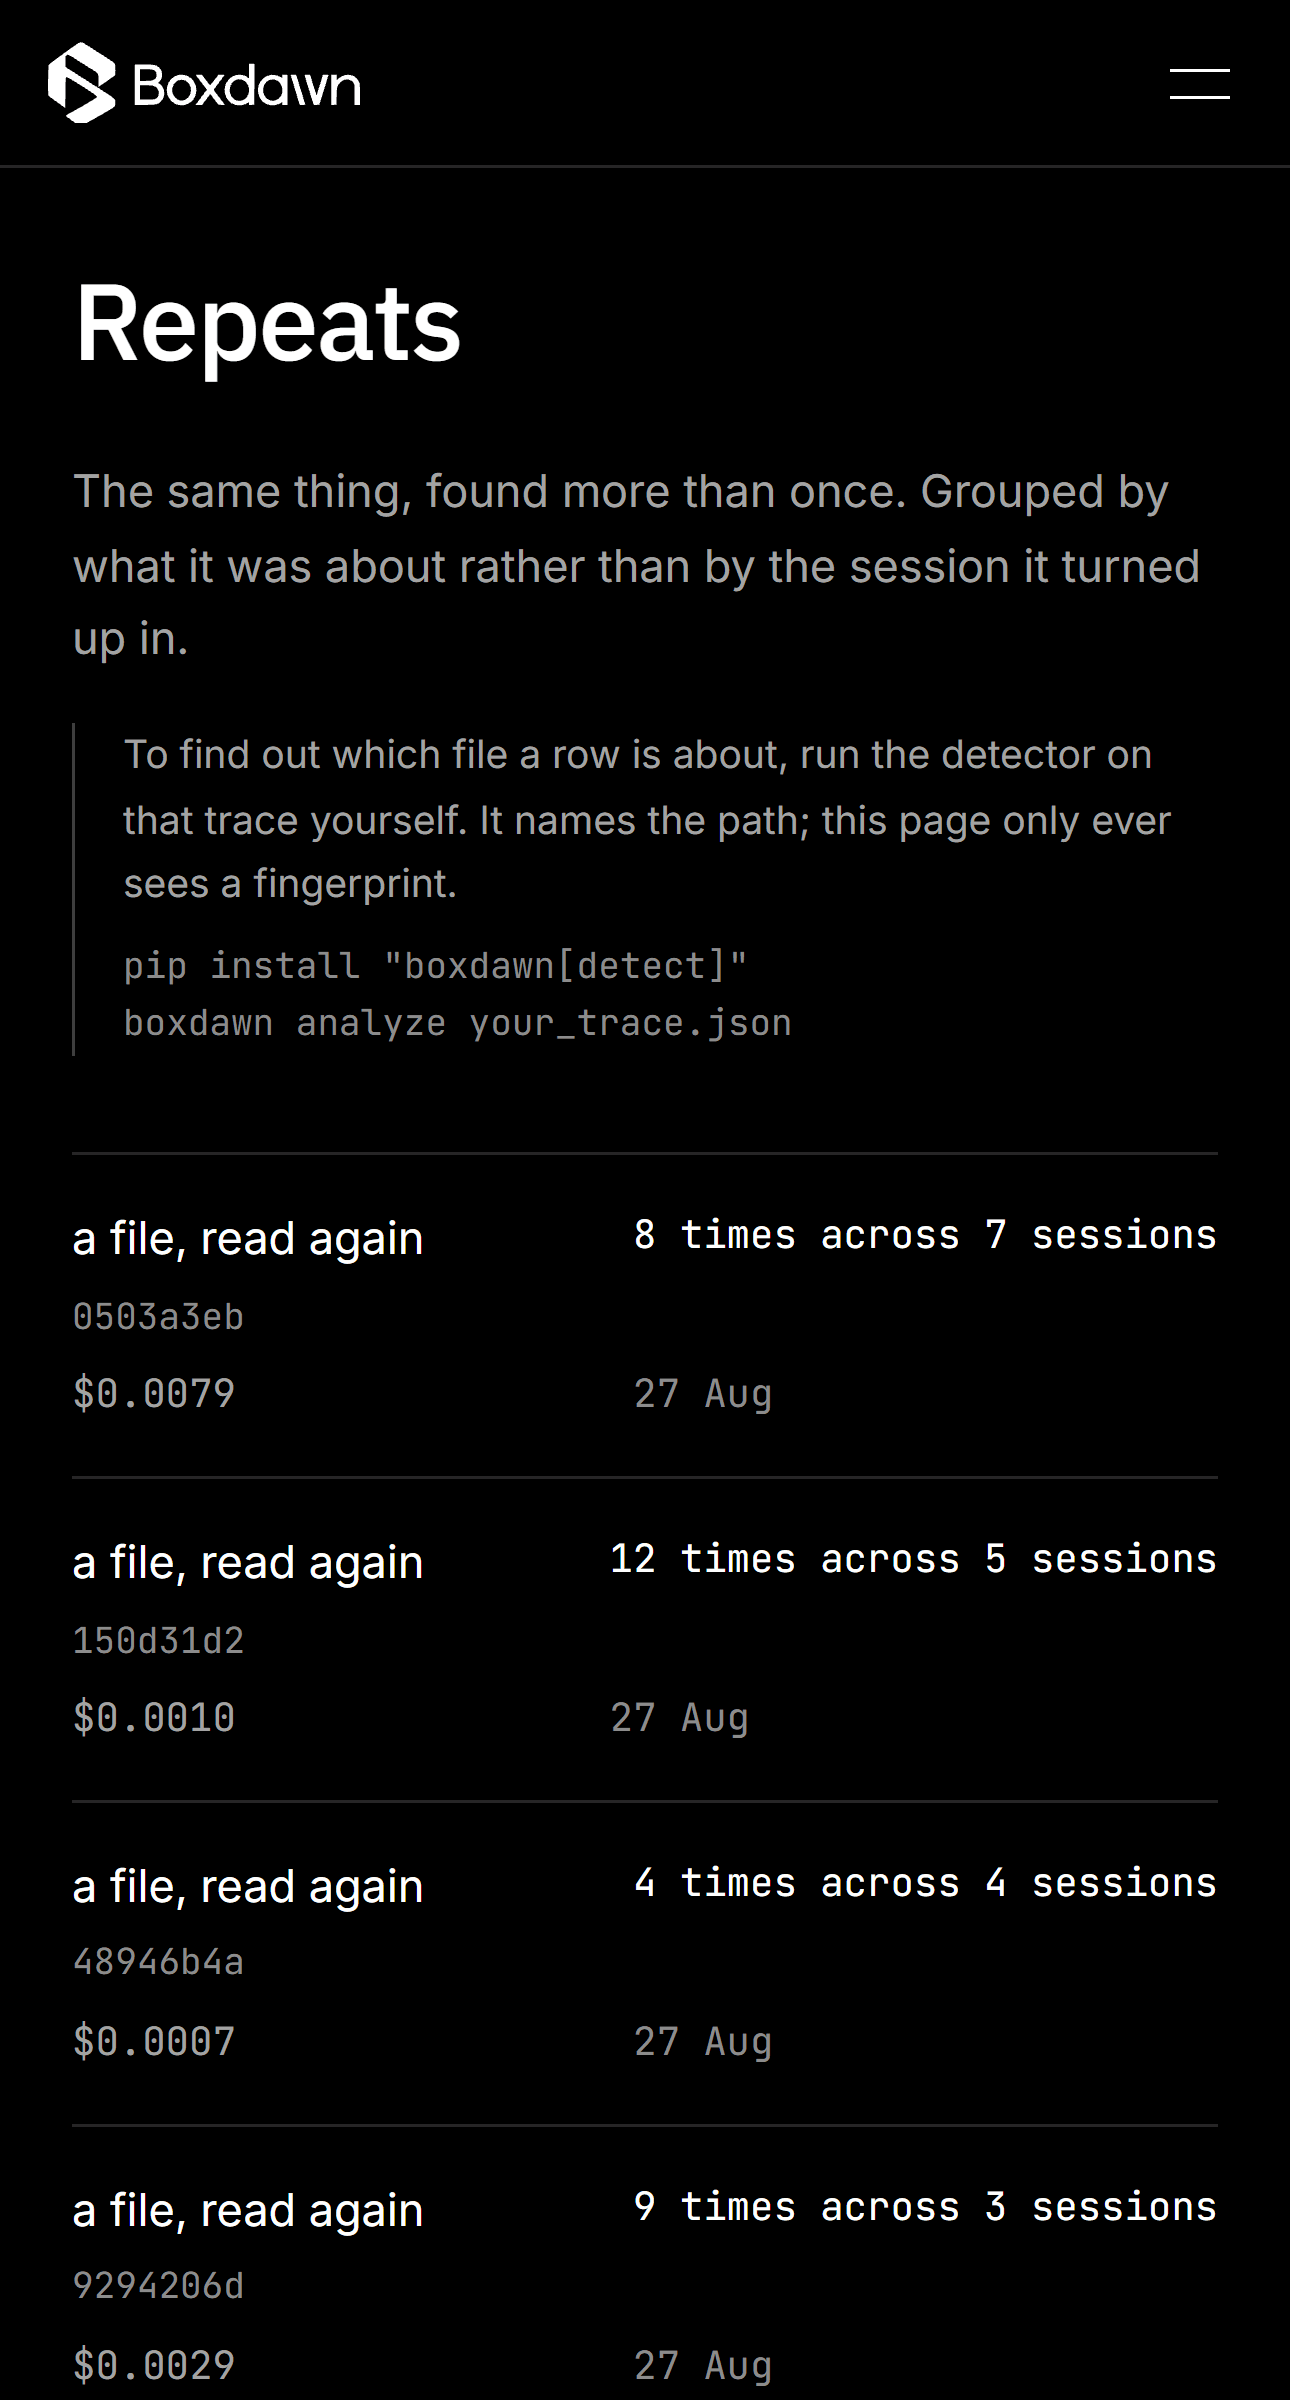
같은 파일이 사이에 쓰기 없이 여러 번 Read 됩니다. 컨텍스트에 이미 있는 것을 잊는 코딩 에이전트에서 흔합니다.
에이전트 바깥의 무언가를 바꾸는 도구가 같은 입력으로 두 번 실행되고, 두 실행이 서로 다른 id 를 돌려줍니다. 두 번째 호출이 두 번째 개체를 만든 것입니다. id 가 같으면 같은 개체이고, id 를 돌려주지 않는 도구는 어느 쪽으로도 판정하지 않습니다.
바이트는 다르지만 의미가 같은 두 메시지 청크(paraphrased 재전송). opt-in LLM-judge 층이 감지 · 기본 비활성 · API 키 필요.
Opt-in 전용 · ANTHROPIC_API_KEY 필요
pingpong은 실제 멀티에이전트 트레이스가 있어야 나타납니다. 단일 에이전트 코딩 세션이나 Toolathlon에서는 발생하지 않습니다.
pingpong 은 구현돼 있지만 위 카드에는 넣지 않았습니다. 리포트가 그 이름을 붙이는 것은 pingpong 검출기가 직접 낸 쌍뿐이고, 낭비율 지표는 이름으로 그것을 제외합니다.
참고: 네 번째 후보 패턴이었던 regen_handoff은(는) 사전 등록 기준을 통과하지 못해 제외되었습니다. Proven / Not Yet 섹션 참조.
Boxdawn이 아는 것.
- read_only
- side_effect
- payload_dependent
- declarative
- LangChain / LangGraph
- CrewAI
- LlamaIndex
- OpenAI Agents SDK
- AutoGen
- Smolagents
- find_repeat_candidates
- find_pingpong_candidates
- find_context_resend
- find_redundant_reads
- find_llm_judge_semantic_duplicates
- Boxdawn Trace JSON
- OTel SDK JSON
- Claude Code JSONL
- Toolathlon JSONL
- OpenInference nested
- RedundancyBench
version: 1
tools:
  search_web:    { category: read_only }
  create_ticket: { category: side_effect, entity_id: response.ticket.id }
  run_python:    { category: payload_dependent }
finalize: { category: declarative }실제 리포트.
# Boxdawn Waste Report

- **trace_id**: `7f309fce-093f-412d-be64-cbd2860481f3`
- **analyzed**: 2026-10-14T09:36:44Z
- **detector params**: φ=0.514345, N=2, model=paraphrase-multilingual-MiniLM-L12-v2

## Cost summary

- **Total analyzed**: $1.972395
- **Total waste (detected)**: $0.901532 (45.7%)
- **Cost accuracy**: `accurate`

Breakdown by detector:
  - repeat: $0.000000
  - context_resend: $0.901532
  - redundant_read: $0.000000
  _Cost attribution across four detectors: repeat, context_resend, redundant_read, semantic_duplicate. A detector that did not run has no row -- absence here is not a measured zero. `repeat` is keyed `provable_duplicate` in the JSON report (same cascade detector, key kept for compatibility). Not the same four as the waste-rate line, which unions repeat, context_resend, redundant_read and duplicate_creation._

## Context resend

Message chunks that appear in the input of two or more LLM calls within this trace, byte-exact by sha256. System-role chunks are exempt. First occurrence of each chunk is not counted (it is the necessary payload); occurrences from the second onward are recorded as resent.

- **events**: 1050 resent chunk occurrence(s)
- **resent input tokens**: 1415467 of 1596520 (88.7%)
- **resent input cost**: $0.901532 of $1.595870 (56.5%)
- **cost accuracy**: `accurate`

### Top offenders (by LLM call)

- span `msg_01S2rTDtWwK9s5G15AiHu3Zf`: 10 resent chunks, 32595 tokens, $0.182613
- span `msg_01GmBJvkryprm1pCB6tMtdc5`: 33 resent chunks, 54433 tokens, $0.053735
- span `msg_013ceb6apNMTyUjDmnSbhMVF`: 74 resent chunks, 80333 tokens, $0.041130
- span `msg_01EszjrD8ho9PWfTYQmsUbsz`: 72 resent chunks, 79982 tokens, $0.039991
- span `msg_011yRBpAFZsnaWQbf7whkZ3a`: 70 resent chunks, 74073 tokens, $0.037036

---
_Note: detection thresholds are frozen at synthetic values (phi=0.514345, N=2); real-trace evaluation is ongoing, but parameters have not been recalibrated. Borderline matches (cosine near phi) deserve human review. This applies to non-tool spans; tool spans use exact sha256 identity._
_Cost is estimated saving potential, not measured: it assumes the wasted output is re-consumed each subsequent turn (structural assumption). Range spans cache-hit (lower) to cache-miss (upper) — two billing outcomes for the same tokens, not a ratio. Attribution uses per-model rates; a model the table does not carry resolves to the nearest named one where an alias exists, and falls back to Sonnet 4.5 otherwise. Only the fallback is reported as a substitution._
2026-10-14에 PyPI 최신 게시본이자 호스팅 분석기가 돌리는 빌드인 boxdawn 0.5.15로, 격리된 환경에서 분석했습니다. 이 블록은 앞서 여기 서 있다가 철회된 실행을 대체합니다. 그 실행은 Claude Code 어댑터가 API 콜 1건의 usage 를 content block 줄마다 세고 있어서 토큰 수와 금액이 전부 과대 집계된 것이었습니다. 그 수치는 0.5.0 부터 0.5.12 까지 소수점 여섯 자리까지 같았는데, 그건 결함이 없었다는 뜻이 아니라 결함이 그만큼 오래 지속됐다는 뜻이었습니다. 수치를 움직인 결함은 셋이고 방향이 같지 않았습니다. 그래서 총액이 한 번도 틀려 보이지 않았습니다. 탐지 건수와 동결 파라미터, 임계값은 하나도 움직이지 않았습니다. 바뀐 것은 같은 탐지 건을 얼마로 매기느냐이지 트레이스 속 낭비가 줄어든 것이 아닙니다. 위에는 분모가 둘 있고 서로 바꿔 쓸 수 없습니다. 45.7%는 입력과 출력을 합한 전체 분석 비용 대비 낭비이고, 56.5%는 LLM 입력 비용만을 분모로 한 재전송 입력 비용입니다. 출처: davanstrien/agent-race-traces 의 claude-code.jsonl 에 boxdawn analyze 실행. CC-BY-4.0으로 공개된 claude-opus-4-7 Claude Code 세션($1.972395 분석). 이 모델은 가격표에 있으므로 달러 수치는 대체 요율이 아닙니다. 공개 트레이스 한 건이지 코퍼스 평균이 아닙니다. 트레이스가 공개되어 있어 위 수치는 전부 재현할 수 있습니다. Cost summary 와 Context resend 절을 보여줍니다. Redundant read 와 LLM-judge(선택형)는 이 트레이스에서는 빈 결과를 냅니다. cost accuracy 는 분석기가 설정하는 필드이며 이 수치에 대한 검증이 아닙니다.
오픈소스입니다. 신뢰 자체가 곧 제품이니까요.
Boxdawn은 MIT 라이선스이며 기본값은 결정론입니다. 네 개의 디텍터(repeat, context resend, redundant read, duplicate creation)가 로컬에서 실행됩니다. API 호출 없음, 가입 없음. 다섯 번째 층 semantic-duplicate LLM-judge는 opt-in 전용입니다: 기본 비활성이며, ANTHROPIC_API_KEY와 CLEW_ENABLE_LLM_JUDGE=1을 명시적으로 설정해야 활성화됩니다. 결정론 층은 같은 트레이스가 들어가면 매번 같은 리포트가 나옵니다.
$ pip install boxdawn$ boxdawn analyze your_trace.jsonOpenTelemetry SDK JSON과 OpenInference 트레이스 익스포트를 지원합니다: LangGraph, CrewAI, AutoGen, LlamaIndex. OTLP proto-JSON은 아직 지원하지 않습니다.
Where we are on the chain.
Boxdawn 은 사슬입니다: monitor → detect → alert → auto-fix → auto-optimize + govern. 오늘 돌아가는 고리는 탐지이고, 서비스로도 라이브러리로도 돌아갑니다. 나머지는 그 순서대로 만들고 있습니다. 어느 것이 어느 쪽인지는 이 페이지에서 확인하실 수 있습니다.
- 호스팅 분석기, 계정 불필요
- 결정론적 탐지기 4종
- 실제 usage 필드에서 뽑은 비용
- 계정 + 프로젝트별 이력
- 일별 낭비율, 세션 날짜 기준
- CI·스크립트용 API 키
- 오픈소스 CLI, 오프라인 실행
- 선택형 의미 분석 패스
- 기준선 알림
- 실시간 모니터링
- 루프 탐지
- 세션 흐름 시각화
- 비용과 함께 지연시간
- 자동 수정
- 자동 최적화
- 정책·거버넌스